

Evaluating Nemotron-3-Diarization on SpokesBiz and DiaBiz
 Author: VoicelabVoiceLab
The new speaker diarization model from Nvidia looks really solid. At Voicelab we’ve just evaluated it on the multispeaker SpokesBiz (650 hours) dataset and it seems to be both more accurate and faster than Nvidia’s Sortformer v2 and PyAnnote 3.1. The results on the two-speaker phone-based DiaBiz dataset (410 hours) are more nuanced with both models from Nvidia clearly outperforming Pyannote 3.1.
SpokesBiz evaluation
SpokesBiz (Pęzik et al. 2023) is a corpus of conversational Polish from pelcra.pl (University of Łódż) comprising over 650 hours in 925 recordings (59 conversations between 1 speaker, 631 featuring two speakers, 222 with 3, 12 with 4 and just 1 with 5 speakers), all manually transcribed and diarized.
The overall (word) diarization error rates (DER) indicate Nemotron-3 as a clear winner. The DER metric is trickier to properly compare than WDER (see https://arxiv.org/pdf/1907.05337), because it measures the exact percentage of time a fragment of speech (or silence) was assigned to the wrong speaker. Its exact value depends on the quality of forced alignment, so we generally prefer word-level assignment error rates as a more intuitive measure for applications of diarization in which we want to attribute transcribed words to speakers. The SpokesBiz results are summarized in Table 1. For this experiment, we required a model’s segment to overlap with the reference word’s timestamp by at least 50% to be considered a match.
| Model | DER | WDER | xRT |
|---|---|---|---|
| nvidia/Nemotron-3-Diarization | 22.5% | 4.8% | 0.0022 |
| nvidia/diar_streaming_sortformer_4spk-v2 | 23.4% | 7.4% | 0.0027 |
| pyannote/speaker-diarization-3.1 | 24.4% | 8.3% | 0.0078 |
Table 1 DER and WDER results on SpokesBiz
Another interesting observation is the ratio of speaker number overestimation and underestimation. Again, as shown in Table 2 Nemotron-3 is significantly more accurate than the other two models with >80% speaker number prediction accuracy rates. The popular Pyannote 3.1 model overestimated the number of speakers over 75% of the time on SpokesBiz. Generally, all three models tend to overestimate rather than underestimate the number of speakers in cases where they actually get it wrong.
| Model | Exactly right | Too many speakers | Too few speakers |
|---|---|---|---|
| Nemotron | 80.6% | 19.1% | 0.2% |
| Sortformer v2 | 51.7% | 48.1% | 0.2% |
| pyannote 3.1 | 23.1% | 75.9% | 1.0% |
Table 2 Predicted number of speakers compared to the reference number on SpokesBiz
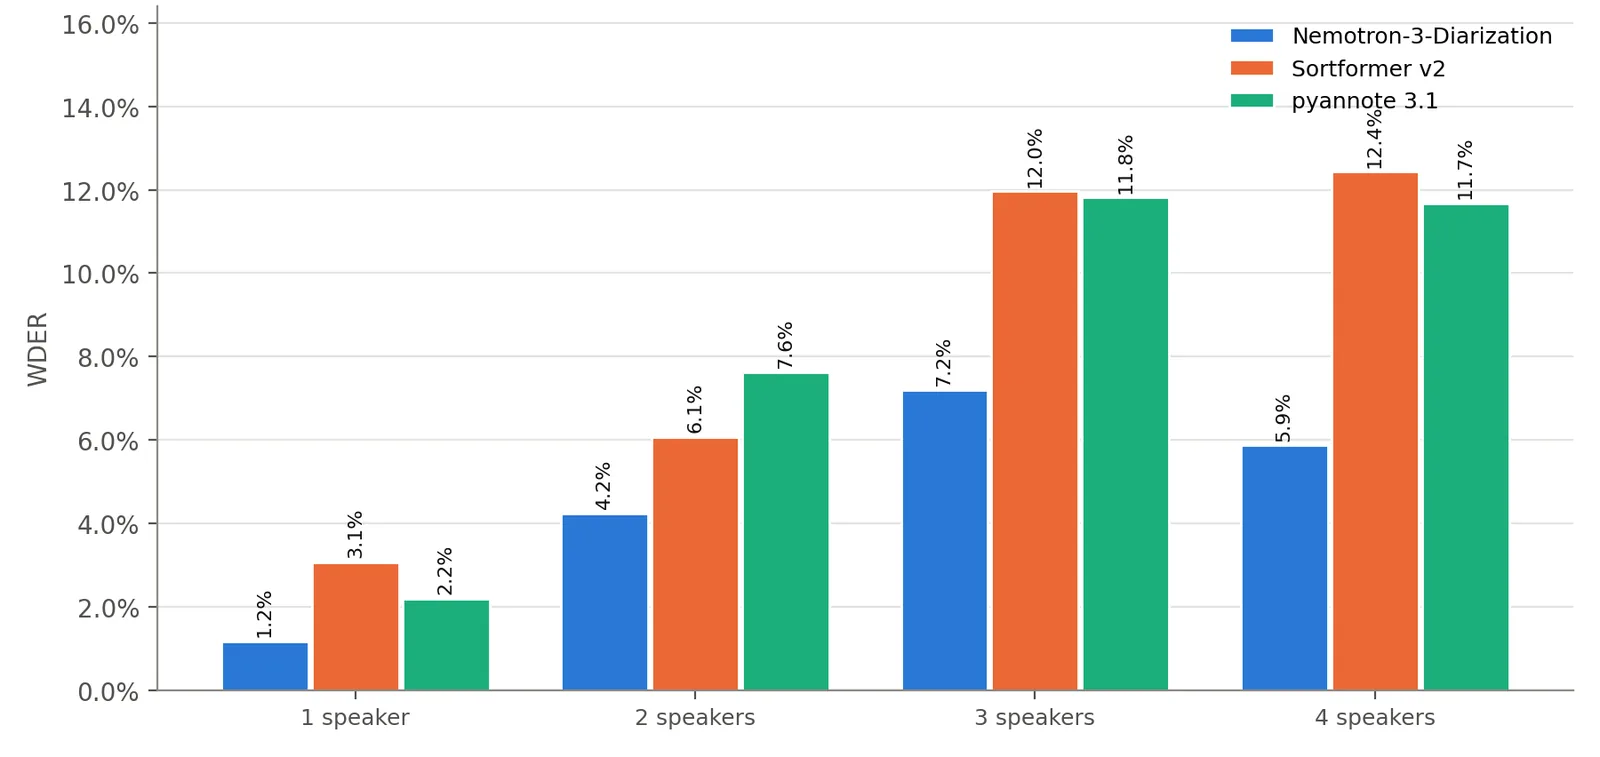
Fig 1 Mean WDER in SpokesBiz by number of reference speakers
Evaluation on DiaBiz
DiaBiz (Pęzik et al. 2020) is another speech database from the University of Łódż, a dialog corpus comprising recordings and annotated transcriptions of phone-based customer-agent interactions in several key business domains (e.g. banking, car, rental, medical care, insurance, debt collection, tourism etc.). The original recordings are stereo. For this experiment we mixed the agent/customer channels and assumed there were always two speakers in each recording. As shown in Table 3 nemotron-3-diarization has the lowest mean WDER on DiaBiz.
| Model | DER | WDER | xRT |
|---|---|---|---|
| nvidia/Nemotron-3-Diarization | 23.3% | 6.3% | 0.0020 |
| nvidia/diar_streaming_sortformer_4spk-v2 | 22.8% | 7.4% | 0.0028 |
| pyannote/speaker-diarization-3.1 | 28.3% | 12.3% | 0.0082 |
Table 3 DER and WDER results on DiaBiz
However, Sortformer V2 seems to have guessed the correct number of speakers in this agent-customer dataset. It is worth noting that some models may have an inherent bias toward predicting exactly two speakers as a safe default.
| Model | Exactly right | Too many speakers | Too few speakers |
|---|---|---|---|
| Nemotron-3 | 90.8% | 9.2% | 0.0% |
| Sortformer v2 | 94.5% | 5.3% | 0.1% |
| pyannote 3.1 | 70.8% | 29.0% | 0.2% |
Table 4 Predicted number of speakers compared to the reference number on DiaBiz
We’re currently evaluating this model on languages other than Polish and in a variety of ASR scenarios.
Author: Piotr Pęzik, Aleksandra Nadzieja, Filip Żarnecki, Wojciech Janowski, Kryspin Musioł, Paweł Czerkas, Anna Dryżałowska, Jacek Kawalec, Andrzej Ciarkowski